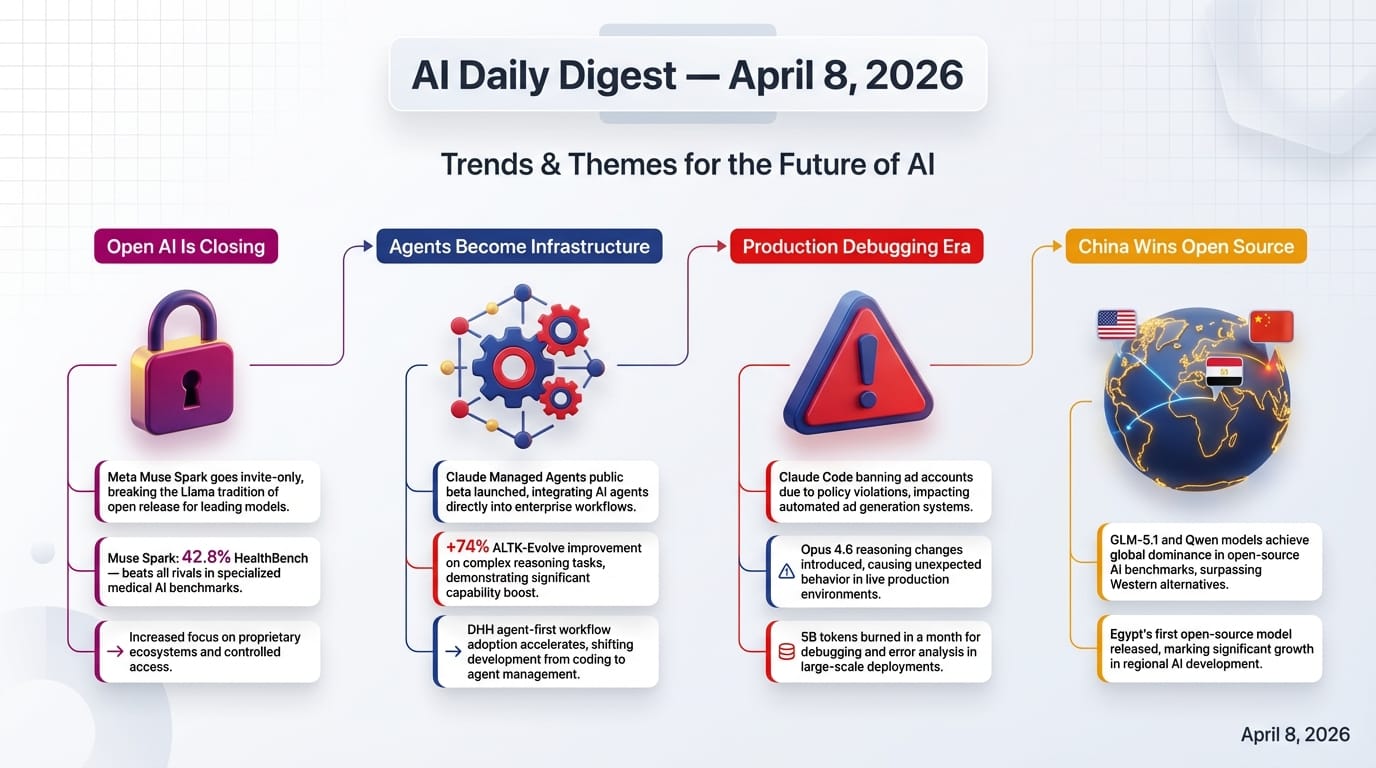
Watch today's digest as a video summary (generated by NotebookLM)
Statistically Speaking
One Thing to Tell Your Friends
TL;DR
Hot off the Presses
Meta's New AI Model Is Here - and It's Not Open Source
Muse Spark is Meta's most powerful AI model yet, built by a new lab under the leadership of Scale AI founder Alexandr Wang - and unlike every Llama model before it, you can't download and run it yourself.
Meta Superintelligence Labs launched Muse Spark today, billing it as their first frontier model on a completely new stack. The model is "natively multimodal" - meaning it can understand and work with text, images, and other inputs at the same time, rather than handling them separately.
Performance is legitimately competitive. On HealthBench Hard (a medical reasoning benchmark where AI tries to answer difficult clinical questions), Muse Spark scored 42.8% - better than Claude Opus 4.6, Gemini 3.1 Pro, and GPT-5.4. On CharXiv Reasoning, which tests how well AI interprets scientific figures and charts, Muse Spark scored 86.4 in Thinking mode, ahead of all major competitors. The trickier "Contemplating" mode, which spins up multiple AI reasoning agents in parallel, hits 58% on Humanity's Last Exam - one of the hardest general-knowledge benchmarks in existence.
Meta says pretraining improvements let Muse Spark reach comparable capabilities with "over an order of magnitude less compute" than Llama 4 Maverick. In plain terms: it's more efficient, not just more powerful. Simon Willison tested the model's tools and found 16 integrated capabilities including web search, a Python code interpreter, and a "visual grounding" tool that can locate individual objects in photos with extraordinary precision - down to individual whiskers on a cat.
The model has gaps. Meta explicitly flagged "long-horizon agentic systems and coding workflows" as areas where it underperforms compared to rivals. Those happen to be two of the fastest-growing use cases in enterprise AI.
The bigger story is what's missing: open weights. Meta's Llama models have been freely downloadable by anyone - a defining feature that made Meta the most developer-friendly of the frontier labs. Muse Spark breaks that tradition entirely. The Register put it bluntly: Muse Spark is "as open as Zuckerberg's private school."
- 42.8% on HealthBench Hard - beats all frontier rivals
- 86.4 on CharXiv Reasoning (Thinking mode)
- 58% on Humanity's Last Exam (Contemplating mode)
- Available at meta.ai with Facebook or Instagram login; Application Programming Interface (API) access is invite-only
Anthropic Launches "Managed Agents" - AI Agents as a Service
Anthropic is now offering to run your AI agents for you. No servers to manage, no infrastructure to configure - you describe what the agent should do, and Anthropic handles the rest.
Claude Managed Agents, now in public beta, is a cloud service where businesses can deploy AI agents that run persistently, scale automatically, and integrate with their tools and systems. Think of it like the difference between buying a car and hiring a driver: instead of figuring out how to set up and run your own AI agent infrastructure, Anthropic runs it for you.
What it includes: secure sandboxed code execution (so the agent can run code without risking your systems), automatic checkpointing (so long tasks don't lose progress if interrupted), scoped permissions (limits on what the agent can access), and persistent sessions that can run for hours or days. Developers define what the agent should do and what tools it can use; Anthropic's infrastructure handles the rest.
Access is through the Claude Console, Claude Code, or a new command-line tool (CLI) - a terminal-based interface for developers.
This puts Anthropic directly in competition with OpenAI, Google, and Salesforce for enterprise AI platform contracts. The key differentiator Anthropic is betting on: safety and reliability guarantees that enterprise IT departments require before letting AI agents touch internal systems.
Try it: Visit claude.ai/managed-agents and request access through the Claude Console.
A Man Gave Claude His 30-Year-Old Game Files. A Weekend Later, It Was Alive Again.
Jon Radoff used Claude Code to reconstruct his 1992 text-based multiplayer game - a complete game world with 2,273 rooms, 1,990 items, and 297 monster types - entirely from old documentation and game captures, with no original source code.
The project on r/ClaudeAI received 2,103 upvotes. Radoff had created Legends of Future Past, a MUD (Multi-User Dungeon - a text-based online multiplayer game popular before the internet went graphical), in 1992. It ran for years, then shut down on December 31, 1999, with the original source code lost.
What he had left: script files in a custom scripting language, a 1996 gameplay capture, a 1998 Game Master manual, and player documentation. What he was missing: any runnable code.
Claude Code reverse-engineered the custom scripting language by analyzing the surviving examples and documentation. It decoded the combat system from the manual, interpreted monster behavior profiles, and then rebuilt the entire game engine from scratch - in the Go programming language, with a React frontend and MongoDB database. A game that took a full team of developers and content creators years to build the first time was resurrected in a weekend.
As Radoff wrote: "A game that I originally coded over six months -with a whole team of Game Masters building the content over years -was resurrected in a weekend."
DHH Has Switched to AI Agents. This Is What Changed His Mind.
David Heinemeier Hansson - the creator of Ruby on Rails (the framework that powers a large chunk of the web), and a vocal skeptic of AI hype - now uses AI agents as his primary development tool. His explanation of why is worth reading.
DHH wrote about his shift in The Pragmatic Engineer newsletter, and it's a template many developers will recognize. He found AI autocomplete tools (the kind that suggest code completions as you type) "genuinely annoying" - they were helpful enough to distract but not reliable enough to trust. He remained skeptical.
What changed: agent-based workflows with powerful models. Instead of AI whispering suggestions, he runs a fast model (currently Gemini 2.5) and a powerful model (currently Claude Opus) simultaneously in terminal windows, with the text editor NeoVim for reviewing the diffs they produce. He describes it as "wearing a mech suit" - the work goes significantly faster, but he's still in control of every decision.
His key observations:
One specific result: a project optimized the fastest 1% of server requests from 4 milliseconds to under 0.5 milliseconds - optimization work that would have been considered economically unjustifiable before, because the human time to do it would have cost more than the server savings.
- Senior engineers benefit most. Experienced developers can validate agent outputs quickly. Junior developers often can't tell when the agent is confidently wrong. Amazon reached the same conclusion and restricted junior programmers from shipping agent-generated code without senior review.
- Beauty signals correctness. DHH argues that elegant code tends to be correct code - if agent output looks messy or complicated, it's a sign something's off. This gives experienced developers a fast intuition filter.
- Ruby on Rails is AI-friendly. Token-efficient syntax, built-in testing, and human-readable conventions make it ideal for agents to generate and humans to review.
512,000 Lines of Leaked Code Reveal How Anthropic Plans to Lock In Your Company
An accidental code leak exposed an Anthropic agent called Conway - and one newsletter's analysis argues it reveals a platform strategy designed to make switching away from Anthropic operationally painful in a way that pricing alone never could.
Nate's Newsletter examined the leaked codebase and argues Anthropic isn't building a chatbot company - it's building the "operating system" for enterprise AI. The analogy: just as Windows became indispensable by hosting applications, Conway is designed to become indispensable by hosting organizational memory.
Conway's architecture includes:
The lock-in mechanism isn't pricing. It's memory. Once an agent has spent months learning how your team works - your naming conventions, your decision patterns, which team members handle what - replacing it means starting that learning process over. The analysis draws a comparison to how Microsoft Office became entrenched: the files weren't portable in practice, even if technically they were.
Connecting today's news: Claude Managed Agents is a public step in this direction. Anthropic Cowork, Claude Code Channels, the Marketplace, and the Partner Network are the others.
- A standalone agent environment separate from the regular Claude chat interface
- Event triggers that let external systems "wake up" the agent when something happens
- Browser control and integration with organizational tools
- Behavioral learning that accumulates context about your company's workflows over time
Trends & Themes

Theme 1: "Open AI" Is Becoming a Selling Point, Not a Given
The trajectory: the leading AI labs are converging on infrastructure and platform ownership as their moat, not model capability or openness. What's harder to replicate is the data, the integrations, and the agents that have been learning inside your organization for a year.
- Meta: first proprietary-only frontier model - Muse Spark is invite-only, hosted-only, and requires a Meta social media account. The Register: "as open as Zuckerberg's private school."
- Anthropic: 512,000 lines of code for an agent "OS" strategy - leaked Conway codebase and today's Managed Agents launch reveal a platform play built on owning infrastructure, not giving away models.
- OpenAI: 15 billion tokens per minute processed - enterprise is 40%+ of revenue and rising; $122 billion committed to AI compute capacity.
Theme 2: AI Agents Are Becoming Real Infrastructure
Each represents a different layer of the agent stack - runtime (Managed Agents), memory (ALTK-Evolve), and workflow integration (DHH's setup). When those layers combine in enterprise deployments, the productivity delta from AI will stop being marginal and start being structural.
- Claude Managed Agents gives enterprises sandboxing, persistent sessions, and checkpointing - the features IT departments require before approving any software for internal use.
- ALTK-Evolve from IBM Research gives agents persistent memory that improves with use - hard tasks improved 74% when agents could accumulate learned guidelines.
- DHH's agent-first workflow describes how a world-class developer has restructured his daily work around agents as his primary mode of development.
Theme 3: The Production Debugging Era Has Begun
These aren't isolated complaints - they're the predictable growing pains of technology moving from hobbyist to enterprise use. AI tools at this capability level can affect real production systems, real ad accounts, and real budgets when they make mistakes.
- A developer's Meta ad account was permanently banned by Claude Code making API calls (67 upvotes) that violated automation terms of service.
- Another developer burned 5 billion tokens with Claude Code in March (65 upvotes) building a financial application - an eye-watering expense reflecting how easily AI-assisted development scales costs.
- Opus 4.6's reasoning effort appears reduced (2,030 upvotes), extending yesterday's story about Claude Code's reduced thinking depth to the flagship model itself.
- A developer waited over a month for Anthropic support to respond (259 upvotes on HN).
Theme 4: Chinese AI Labs Are Winning the Open-Source Race
Previously: April 7 - Z.ai released GLM-5.1, a 754-billion-parameter model under MIT license, the largest open-source AI model ever released.
- The ATOM Report highlights the "sheer dominance of Chinese labs" in open-source AI output.
- Three separate r/LocalLLaMA threads discuss Qwen 3.5 variants: a 122B model outperforming alternatives on Apple Silicon, an uncensored 35B variant (110 upvotes), and a cache reuse bug being tracked - the behavior of a mature, widely-deployed model.
- US labs are shifting to proprietary-only (Meta's Muse Spark, Anthropic's enterprise infrastructure), while Chinese labs continue releasing powerful models anyone can download, run locally, and modify freely.
Creative AI & Media
Developer Tools & Infrastructure
Research & Models
OCR Is Getting a Major Upgrade - By Abandoning How Language Models Work
OCR - Optical Character Recognition - is the technology that converts images of text into actual text. It's how your phone can scan a receipt, or how a hospital converts paper records into searchable data. Every modern OCR system works the same way: it generates one word (technically one "token") at a time, left to right, top to bottom.
This has three problems. First, it's slow for long documents - every page requires thousands of sequential steps. Second, errors compound: if the system misreads an early word, it affects its guesses for later words. Third, and most interesting: the system "cheats." Because it's generating language, it uses knowledge about which words normally follow which other words - so it fills in what it expects to see rather than what's actually there.
MinerU-Diffusion from Shanghai AI Lab's OpenDataLab proves this with a clever experiment. They scrambled the text in documents - keeping the visual layout but randomizing the words - and tested two systems. Traditional OCR failed badly because the words no longer "made sense" linguistically. MinerU-Diffusion was unaffected because it reads visually, not linguistically.
Speed: 3.26 times faster than current tools. Accuracy: 99.9% relative to the best existing systems.
Gemma 4: Under the Hood
Google's Gemma 4 model family - covered in yesterday's digest as a new open-source release - got an architectural deep-dive today from machine learning researcher Maarten Grootendorst. The visual guide breaks down how the models actually work.
The key design choice: the models use a "sparse" approach called Mixture of Experts (MoE) for the largest variant (Gemma 4 26B A4B). Of the model's 26 billion parameters, only 4 billion are activated for any given input. This is like having a team of 26 specialists but only involving 4 of them for each task - you get the breadth of the full team's knowledge without the cost of involving everyone every time.
Compact variants (E2B/E4B) store per-layer embeddings on device flash storage rather than RAM - enabling more capable models to run on phones with limited memory.
Community update: r/LocalLLaMA discussions today showed ongoing issues getting Gemma 4 into the popular GGUF (compressed model) format for local use, with 406 upvotes on a thread tracking the llama.cpp pull requests needed to support it.
AI Gives Worse Information to the People Who Need It Most
This is a significant equity problem. LLMs (Large Language Models - the technology behind ChatGPT, Claude, and similar tools) are frequently marketed as democratizing tools, providing information access to people who couldn't otherwise afford doctors, lawyers, or financial advisors.
The reality, according to this research: the users who most need reliable AI-provided information - those least equipped to fact-check it independently, or access alternative expert sources - receive systematically worse outputs. The pattern held across three state-of-the-art models on two different datasets measuring truthfulness and factuality.
The mechanism isn't fully established. One likely factor: training data is overwhelmingly English-language and US-centric, so the models have weaker signal for interpreting non-standard phrasing or questions about non-US contexts.
Someone Put a Neural Network on a 1983 Commodore 64
The result works. It generates one word approximately every minute. The project on GitHub received 32 upvotes on r/LocalLLaMA. The model has 25,000 parameters - for reference, GPT-4 has roughly 1.8 trillion, making this implementation about 72 million times smaller.
The reason this is interesting isn't practical. It's architectural. The transformer design (the "T" in GPT) is elegant enough to implement on hardware 40 years old with 64 kilobytes of RAM. The gap between what's theoretically possible and what's computationally practical is entirely about hardware and data, not about the fundamental approach being right or wrong.
Business & Industry
Surprising & Under-the-Radar
Signals to Track

HappyHorse: An Open Video Model That Beat the Competition
A Chinese AI model called HappyHorse reportedly beat SeedDance (one of the leading AI video generation models). A post on r/LocalLLaMA (35 upvotes) noted the team may release model weights publicly. If it does, it would be the highest-capability open video generation model available for local use - significant for creators who need local video generation for privacy or cost reasons.
VoxCPM2: A New Text-to-Speech Model Worth Testing
OpenBMB released VoxCPM2, a new open-source text-to-speech model available on Hugging Face. Community testing on r/LocalLLaMA (27 upvotes) described it as competitive with existing options. Text-to-speech is one of the areas where open models have consistently lagged behind commercial tools - VoxCPM2 may be narrowing that gap.
Try it: Live demo at huggingface.co/spaces/openbmb/VoxCPM-Demo. Model weights at huggingface.co/openbmb/VoxCPM2.
Egypt's First Open-Source AI Model
Horus, described as the first open-source AI model built in Egypt, was shared on r/LocalLLaMA today (270 upvotes). Available at tokenai.cloud/horus. The significance is less about Horus's current capabilities and more about the signal: AI development is no longer concentrated in a handful of US and Chinese labs. The geographic distribution is widening.
pi + Earendil: Armin Ronacher Enters the Coding Agent Race
The pi agent moving to Earendil means one of the most credible open-source figures in the Python ecosystem is now actively working on the AI coding tools problem. Given how Flask, Click, and Jinja2 evolved - starting as personal tools, becoming industry standards - this is a project to watch for developers who care about coding agent quality and openness.






Member discussion