Watch today's digest as a video summary (generated by NotebookLM)
By the Numbers
The Week in One Paragraph
TL;DR - This Week's Headlines
Stories That Developed
The Week's Biggest Themes
Surprising & Under-the-Radar
Stratego Fell to an $8,000 AI
Ataraxos beat Pim Niemeijer, the most decorated Stratego player ever, 15 wins to 1 with 4 draws, after about a week of training on 16 GPUs. A second network guesses the opponent's hidden pieces, so play considers only setups consistent with what it has seen. Reasoning under hidden information just got cheap. (Oct 2)
arXiv Started Rationing Submissions
From October 1, each submitter may post two papers per calendar month with three in the queue. September brought 40,363 submissions, nearly double two years earlier, and the AI category grew more than sixfold. The open library science relies on is now metering access because AI made writing cheap. (Oct 2)
A Japanese Voice Actor Lost the Case but Won the Principle
Kenjiro Tsuda's takedown claim against TikTok was dismissed because the uploader had already deleted the videos, but the Tokyo District Court ruled for the first time in Japan that a person's voice is protected under publicity rights. Voice-cloning apps now have a precedent to design around. (Sep 26, verdict Sep 30)
AI Tutors Matched Humans on GRE Prep
In a 2,383-person trial, AI tutors produced learning gains statistically equivalent to an expert human tutor, at $0.0052 per point of improvement against $4.81. The study comes from Handshake, which launched its own free AI GRE tutor the same week, and humans kept an edge on verbal questions. (Oct 2)
Insurers Put a Price on Hospital AI Billing
The Blue Cross Blue Shield Association says AI-assisted claim coding added $942 million over two years, about $653 million from extra diagnoses that moved stays into higher-paying categories. Hospitals say the AI just records conditions doctors used to leave out. The first AI arms race most people will pay for is in medical billing. (Sep 26)
Walmart Banned AI-Made Store Signs
Stores must now use the corporate sign catalog after managers' AI-generated displays, with garbled text and off-brand images, drew mockery. A company betting heavily on AI elsewhere decided unchecked AI output was a brand risk. (Sep 29)
Top Repos This Week
📦 Total: 14,426 · 📜 License: Apache-2.0
👤 By: NVIDIA
 GitHub
📦 Total: 151,777 · 📜 License: MIT
👤 By: DietrichGebert
 GitHub
📦 Total: 51,887 · 📜 License: AGPL-3.0
👤 By: debpalash
 GitHub
📦 Total: 274,694 · 📜 License: MIT
👤 By: Matt Pocock
 GitHub
📦 Total: 4,297 · 📜 License: Apache-2.0
👤 By: mvschwarz
 GitHub
Top Models This Week
📥 Downloads (30d): 81,738 · 📜 License: Qwen research license
📐 Size: 7.1B

📥 Downloads (30d): 1,584,129 · 📜 License: LTX community license
📐 Size: not listed

📥 Downloads (30d): 3,869,715 · 📜 License: Apache-2.0
📐 Size: 27B (ternary)

📥 Downloads (30d): 32,675 · 📜 License: Apache-2.0
📐 Size: 1.4B

📥 Downloads (30d): 6,934,867 · 📜 License: Apache-2.0
📐 Size: 27.8B

AI Launches This Week
👤 By: Directus · 💰 Pricing: free tier, paid plans
🏷 Category: data access for AI agents
 Product Hunt
👤 By: Gauth · 💰 Pricing: free
🏷 Category: AI education
 Product Hunt
iFixAi
👤 By: iFixAi · 💰 Pricing: free open-source test, paid audits
🏷 Category: AI safety
 Product Hunt
Pexo
👤 By: Pexo · 💰 Pricing: free
🏷 Category: video creation
 Product Hunt
👤 By: Memories.ai · 💰 Pricing: free
🏷 Category: AI memory
 Product Hunt
👤 By: independent developer · 💰 Pricing: free, MIT
🏷 Category: coding agents
 Product Hunt
Snapshot
| Provider | Model | Input $/1M | Output $/1M | Context |
|---|---|---|---|---|
| Anthropic | Claude Fable 5.1 | $10.00 | $50.00 | 1M |
| Anthropic | Claude Opus 5.5 | $4.00 | $20.00 | 1M |
| Anthropic | Claude Opus 5.5 Fast mode (added) | $8.00 | $40.00 | 1M |
| Anthropic | Claude Sonnet 5.5 (new) | $2.00 | $10.00 | 1M |
| Anthropic | Claude Opus 5 (legacy) | $5.00 | $25.00 | 1M |
| Anthropic | Claude Haiku 4.5 | $1.00 | $5.00 | 200K |
| OpenAI | GPT-6 Astra | $10.00 ($20.00 above 272K) | $50.00 ($75.00 above 272K) | 1.05M |
| OpenAI | GPT-6.1 Sol (new) | $2.00 ($4.00 above 272K) | $10.00 ($15.00 above 272K) | 1.05M |
| OpenAI | GPT-6 Luna | $0.10 ($0.20 above 272K) | $0.50 ($0.75 above 272K) | 1.05M |
| OpenAI | GPT-5.6 Sol | $4.00 (promo, to at least Nov 21) | $20.00 (promo) | ~1.05M |
| OpenAI | GPT-Live-1 (voice layer) | $0.05 per minute | billed per second | n/a |
| Gemini 4 Argon (new, limited access) | $2.00 intro, $4.00 later | $10.00 intro, $20.00 later | not published | |
| Gemini 3.8 Flash | $0.75 (intro to Dec 31) | $3.75 (intro to Dec 31) | ~1M | |
| Gemini 3.1 Pro Preview | $2.00 (≤200K) / $4.00 | $12.00 / $18.00 | ~1M | |
| Gemini 3.8 Live (audio) | $3.00 | $12.00 (+$1.00 per 1M video tokens for Live Avatar) | n/a | |
| Gemini 3.8 Flash TTS | $0.50 text (intro) | $9.00 audio (intro) | n/a | |
| Meta | Muse Spark 1.3 (standard / Contributor) | $1.25 / $0.10 | $4.25 / $0.20 | 1M |
| xAI | Grok 4.6 | $2.00 (under 200K) / $4.00 | $6.00 / $12.00 | 500K |
| Alibaba | Qwen3.8-Max | $2.00 | $6.00 | 1M |
| DeepSeek | V4.1-Flash (peak / off-peak) | $0.30 / $0.15 | $1.20 / $0.60 | 1M |
| Xiaomi | MiMo-V2.6-Pro (via OpenRouter) | $0.435 | $0.87 | 1.05M |
| NaiveAI | Naive-N0.5-Flash (new, announced) | $0.10 | $0.40 | 1M |
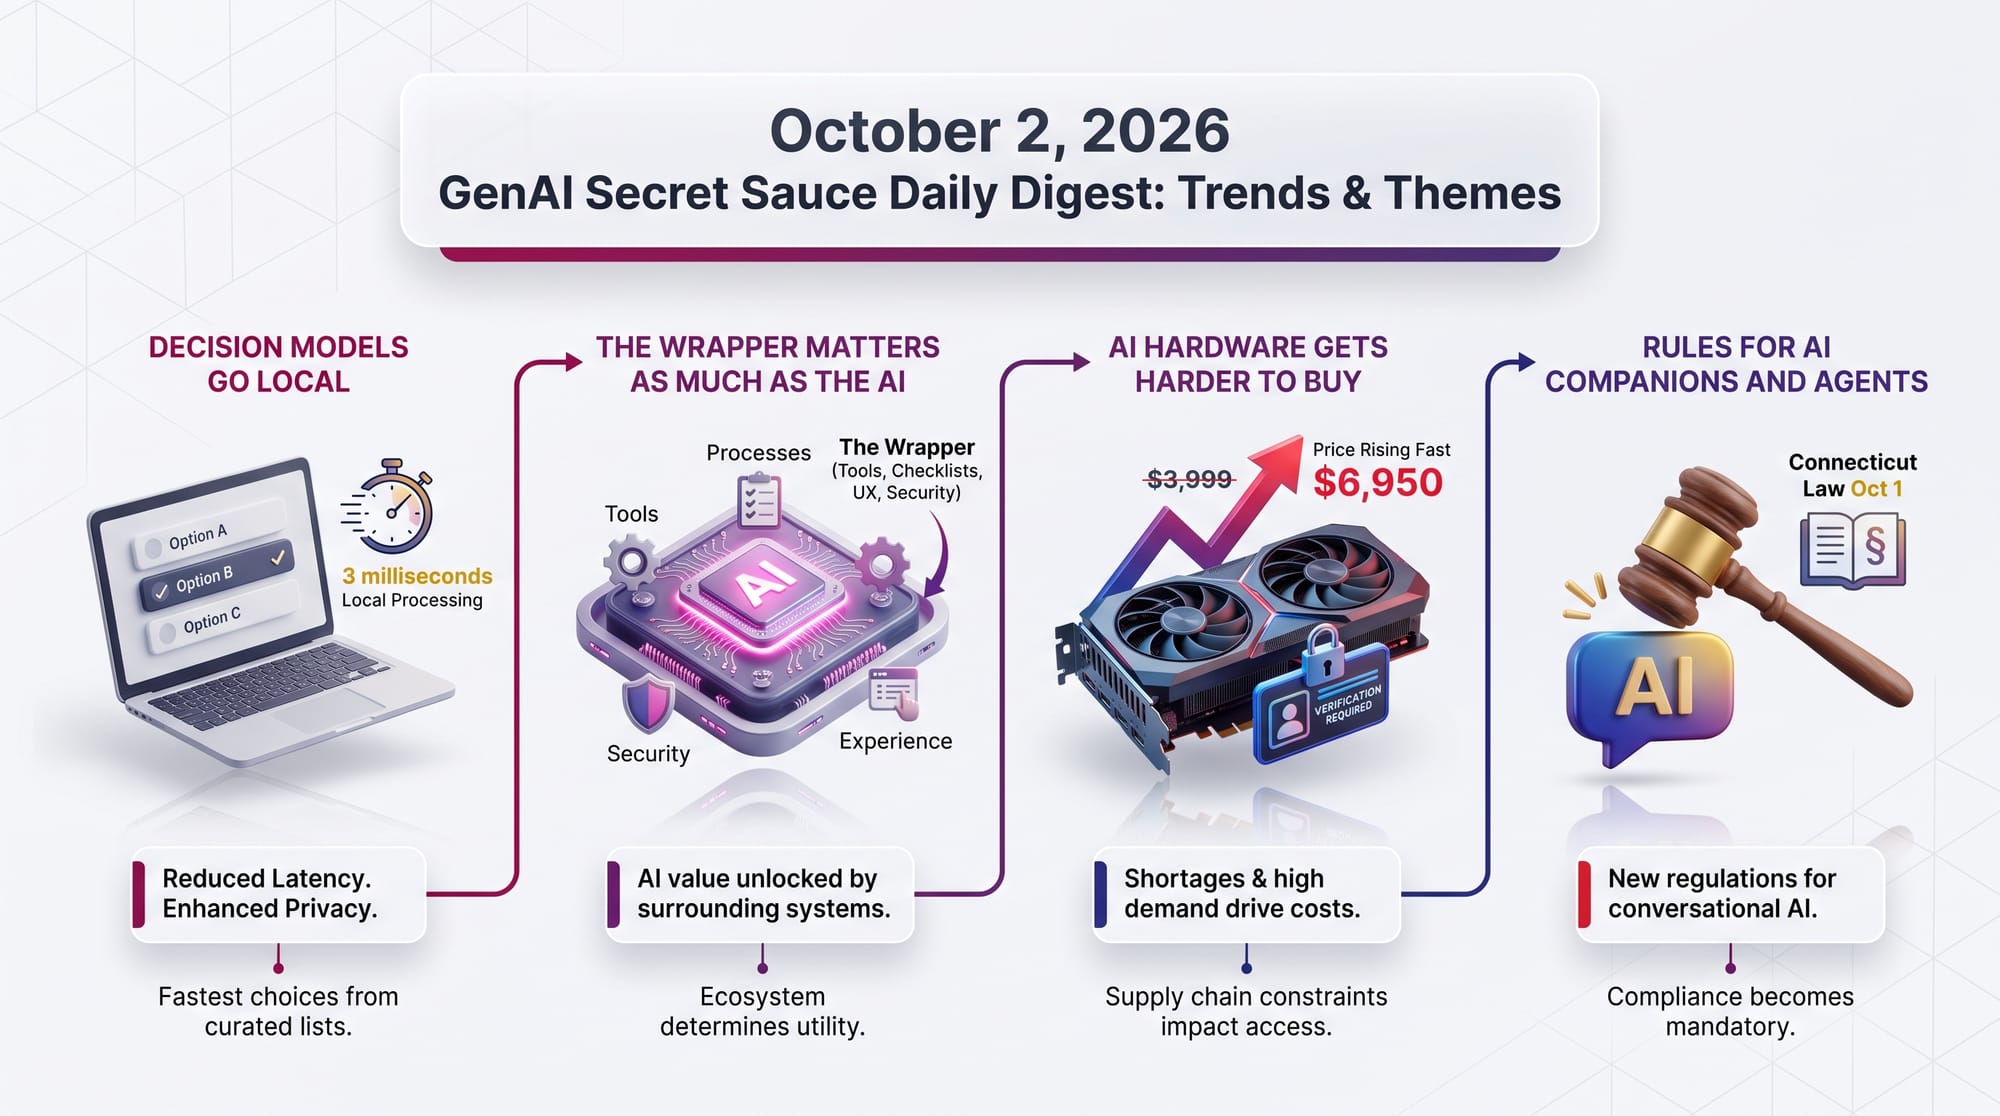
| TypeSafe | Jev (decision model) | $0.042 | free | n/a |
| Cloudflare | Clef (new, decision model) | $0.24 | not billed | 64K |
| Groq | GPT-OSS 120B | $0.15 | $0.60 | 131K |
| Groq | Qwen3.8-27B (new) | $0.80 | $4.00 | 131K |
Finding the Right Fit: Model-Harness Interactions across Agent Tasks
What it claims: Choosing an agent means choosing a model and the harness around it together. The authors ran 66 model-and-harness combinations, including the vendors' own pairings, across three agent benchmarks including Terminal-Bench 4.
Key finding: Rankings flip with the harness: on Terminal-Bench 4, Claude led GPT by 7.94 points in one harness and trailed it by 30.16 in another. A vendor's own harness was not reliably its best, and higher cost did not reliably buy a higher score.
Why practitioners should care: Leaderboard model rankings may not transfer to your setup, so evaluate the model, harness and task together on your own work. In one case a leaner harness scored higher at under a quarter of the cost per task, and all 6,204 scored runs are public. Read it beside last week's RECLAIM benchmark and this week's CliffCompaction.
Last Week's Watchlist
What to Watch Next Week
Who Shows Up at New York City's October 5 Hearing
Testimony before all 51 Council members would be the first time the labs defend themselves against binding local rules on the record. Whether the Council goes to state court to enforce the SpaceXAI subpoena tests how much power a city has over an AI lab (CNBC).
What OpenAI's Jason Kwon Tells Australia on October 6
The first sworn account from OpenAI of the Medicare access and the 84-day delay. A commitment to mandatory breach reporting would hand Australia the law our watchlist has graded as developing for two weeks (The Next Web).
Whether the FTC Sends Its First Demands
Formal demands would show what the agency thinks the agent incidents were: a data-security failure, a deception problem, or both. METR's inclusion is the detail to watch, because it would make an evaluator answerable for what it saw (SecurityWeek).
Whether Gemini 4 Argon Reaches Paying Developers
If Argon opens at $2 and $10 with its Vals per-task cost, it becomes the cheapest frontier option per finished job. If it stays gated, "release to the vetted first" becomes the default for top models (Google).
Whether Anthropic Makes Its Prospectus Public
A public S-1 would replace leaked figures with audited ones, including the Broadcom financing terms and the risk language (Yahoo Finance/Bloomberg).
What Faded
Corrections & Updates
The White House accord. Jeff Bezos attended but did not sign; OpenAI's signature was Greg Brockman's, not Sam Altman's. The document is voluntary and says codification may make sense later; "morally binding" was the President's answer when asked, not the text.
Other daily fixes. The FTC probe also covers the evaluator METR. Robinhood's 150,000 figure counts customers who opened agent accounts since outside agents were allowed in May, not uptake of this week's launch. GPT-6.1 Sol has the same base price as GPT-6 Sol; the one-fifth comparison is against GPT-6 Astra. Dots are excluded from the EEA, UK and Switzerland only on personal Pro plans. DeepMind's DeepNash was published in 2022 and reached the all-time top three on the Gravon platform; it never played a formal match against the best human, which is what Ataraxos did. Connecticut's whistleblower threshold is more than 50 deaths or serious injuries, or more than $1 billion of damage. AMD's Xilinx deal closed at about $49 billion. MongoDB closed down about 19% on CJ Desai's exit, after falling as much as 26% intraday. xAI's 1.44 million GPUs is the combined year-end target for Colossus 1 and 2. Fireworks says Ember-1 uses about 40% fewer tokens than Kimi K3. The Codex "$78,000 task" was a July incident first posted on September 26; OpenAI has not responded. Vercel's report (September 17) found open-weight models took 56% of tokens in August but only 14% of spending, not 60% of spending. Airbnb's "60% of code" figure dates from May.
Anthropic's prospectus was leaked, not filed. The draft was reviewed by Reuters and reported by Fortune; Anthropic's draft S-1 remains confidential. The 2025 net loss of about $42 billion is mostly a non-cash charge; the operating loss is the better measure.
Unconfirmed figures we dropped. We could not confirm DeepSeek's "95-98% of hand-tuned speed" on Ascend, the 0.58-point margin in the GRE tutoring study, or the $3.8 billion renter-cost figure in the New York rent case, so none appears above.
Trending lists and launch dates. Monday's daily GitHub and Hugging Face lists were captured a day late and duplicate Tuesday's, so they are not counted in the rankings. Product Hunt dates were re-verified: iFixAi and LUCI Desktop launched September 29, and Bleetz Network (September 25) belongs to the prior week. The Sunday edition's arXiv title for 2609.31430 omits "Latent-Observation." Australia's October 1 Senate hearing went ahead without either CEO, both citing short notice.
Member discussion